ALNETS
Higher Ed & Research AI · Core HubCloud & On-Premise Dual-Engine · Software & Hardware Evolution

Higher Ed & Research AI Gateway & Compute Governance

The Gateway to Campus AI: Unified Ingestion of Cloud & Local Models, AiW 6-GPU Compute Foundation, Zero IP Leakage, and Multidisciplinary AI Diversity

Eliminate departmental model silos, unsecured key sharing, runaway token consumption during student labs, and confidentiality risks with research data. Centered on the unified AI Gateway, this solution aggregates both public cloud LLMs and on-premise private models (anchored by AiW 6-GPU compute hosts and AiW-V workstations). On-premise models ensure exam banks, unpublished research, and national grants stay 100% air-gapped on campus, while allocating tailored models across computer science, engineering, medicine, and humanities for multidisciplinary AI diversity.

"The gateway is far more than a cloud proxy: it is a dual-engine hub unifying commercial cloud LLMs and on-premise compute. It locks down confidential academic assets on local AiW 6-GPU hosts while allocating tailored models across diverse disciplines."
Dual-EngineUnified cloud commercial & on-premise local model catalogs
Zero LeakageAiW 6-GPU local model air-gap: exams & papers stay on campus
Multi-DisciplineTailored models per department (CS, STEM, Medicine, Humanities)
4-Tier QuotasUniversity, department, lab/course & user hierarchical quota limits
Higher Ed & Research AI Gateway & Compute Governance
Campus Network & Computing Center: Real-time telemetry of university AI API traffic and department token quotas● Campus AI Gateway: Governed & Active

PAIN POINTS

Four Critical Roadblocks in Campus AI Adoption

As campus AI expands from individual experiments to university-wide curriculum, unmanaged direct access quickly triggers operational crises:

01

Cloud-Only Myth & Teaching Data Leakage

Institutions mistakenly assume AI can only be consumed via public cloud APIs, risking sensitive exam questions, unpublished research papers, and student records being leaked or scraped for training.

Solution: Gateway natively manages on-premise local models, keeping sensitive academic assets 100% on-campus.
02

One-Size-Fits-All & Lack of Model Diversity

Different faculties have distinct AI needs: CS requires open models with fine-tuning control; medical labs require air-gapped domain models; humanities need general assistants. Uniform setups stifle innovation.

Solution: Role-based model routing allocating local compute to CS and cost-effective cloud models to humanities.
03

Chaotic Billing & Grant Audit Friction

Professors pay out of pocket using personal credit cards. Upstream platforms only provide lump-sum statements, making it impossible to attribute consumption to specific national grant codes for finance audits.

Solution: Bind API keys directly to research grant codes with granular PDF audit statements.
04

Runaway Token OPEX & Student Lab Crashes

Paying cloud token rates for high-frequency coding labs creates unsustainable OPEX. Furthermore, a single student with an infinite request loop can deplete class funds and halt lab sessions.

Solution: Deploy on-premise AiW 6-GPU hosts for zero marginal token cost, paired with instant circuit breakers.

VALUE PILLARS

Four Core Value Pillars for Academic Institutions

Engineered for dual-engine orchestration, teaching IP protection, multidisciplinary diversity, and cost predictability:

01

Unified Ingestion · Cloud & Local Dual Engines

The gateway is far more than a cloud proxy: it unifies public commercial LLMs with on-premise private models (powered by AiW 6-GPU hosts and workstations running 70B/DeepSeek-R1). Exposes standard OpenAI-compatible endpoints with seamless failover.

02

Zero IP Leakage · On-Premise Air-Gapped Compute

Critical academic assets never leave campus: final exam banks, unpublished papers, defense research, and student records are forced to on-premise AiW 6-GPU compute. Raw prompts remain 100% within the local network, functioning reliably even during WAN outages.

03

Tailored Allocation · Multidisciplinary AI Diversity

Move beyond rigid one-size-fits-all rollouts: CS gets local open-weights for deep programming and fine-tuning; medical labs get dedicated air-gapped models; general humanities get cloud assistants; campus administration gets private RAG QA engines.

04

Phased Scaling & Zero Marginal Token Cost

Start lightweight with gateway-level model consolidation to govern keys and accounts. As student lab traffic and confidential workloads grow, smoothly expand on-premise AiW 6-GPU compute hosts—delivering zero marginal token costs for heavy continuous usage.

PHASED ROADMAP

Four-Stage Maturity Model for University AI

Begin by installing the campus AI "meter and breaker panel", then expand on-premise compute pipelines:

Stage 1 · Gateway KeyCore Foundation

Unified Access & Token Governance

Deploy the Enterprise AI API Gateway. Consolidate upstream vendor accounts, issue scoped API keys per college and course, and enforce strict token ceilings.

Stage 2 · Campus RAGOptional Module

Private Campus Knowledge & SOPs

Ingest syllabi, university policies, and academic papers into private on-premise vector databases. Ground answers with verified citations for 24/7 staff and student inquiries.

Stage 3 · Local ComputeResearch & CS Labs

AiW 6-GPU Local Model Foundation

Deploy AiW 6-GPU parallel compute hosts. Run high-throughput 70B open-weight models on campus, supporting high-density coding practicums and confidential defense projects with zero recurring token fees.

Stage 4 · Agent SandboxesFaculty Sandboxes

24/7 Dedicated Agent Runspaces

Equip senior professors with 10W ultra-low-power AiA host appliances. Run continuous 24/7 literature scanners, lab data parsers, and code audits without tying up personal laptops.

CAMPUS ARCHITECTURE

Three-Tier Campus Ingress & Physical Security Boundaries

Adhering to strict engineering boundaries: transparent intranet routing, hardened public egress, and air-gapped confidential compute:

FULL TECHNICAL ARCHITECTURE & TOPOLOGYCloud & On-Premise Dual-Engine Architecture

Campus AI Model Access & Data Flow Architecture: Cloud & On-Premise Dual Hub

The API Gateway aggregates cloud frontier LLMs and local on-premise models (powered by AiW 6-GPU compute hosts and workstations). Allocates tailored models across departments while keeping curriculum and grant data 100% on-campus.

OFF-CAMPUS CLOUD AI MODEL SERVICESTLS Encrypted / Egress TunnelsMainstream Cloud LLMs (DeepSeek / Qwen)Campus-Wide Courses & General AssistanceToken Metering · High Concurrency Cost-EffectiveFrontier Academic Models (Claude / OpenAI)Advanced Reasoning & Benchmark ResearchEncrypted Egress · Zero Account CollisionSECURITY & COMPLIANCE PRINCIPLES1. Zero inbound public direct access to campus LAN2. Exams & confidential data forbidden on public cloud LLMsEncrypted WAN EgressAiR AI Cloud Gateway RouterCampus Edge Boundary · 12W FanlessHardened TLS Tunnel · Drops ProbingWANLANGoverned Hub Ingress★ CAMPUS AI GATEWAY HUB · DUAL-ENGINE SCHEDULERALNETS Enterprise AI API GatewayHardware UpcomingDual-engine: Cloud LLMs & local models · Scoped models per org · Zero IP leakageCloud & Local HubInstant Fail-SafeAiW 6-GPU LocalScoped Multi-ModelGateway Wire-Speed DispatchCAMPUS CORE BACKBONE SWITCH · 802.1Q VLAN ISOLATEDWire-Speed ForwardingComputer Labs & Courses150+ Students Programming Practicum• Scoped cloud/local models per course• 500K Tokens / student ceiling• 10x error loops trigger circuit break• Semester-end automated key revocationStudent Lab Flow (Blue)Confidential Research LabsNational Grants & Defense Projects• Sensitive data forced to local AiW 6-GPU• 100% curriculum & paper privacy• Dedicated high-param local model• Key bound to grant code for financeConfidential Flow (Green)AiW 6-GPU Host / AiW-V WorkstationCampus Local Model Cluster · 70B• Gateway unified on-premise model serving• 100% curriculum & research privacy• Multi-GPU concurrency · 0 token fee• Supports model tuning & full controlPrimary Local Model · 6-GPUFaculty Desks & AdministrationAiA Host + Campus RAG Hub• 10W 24/7 persistent literature agent• Syllabi & policy grounded answers• 24/7 staff support without PC load• Physical OS-level sandboxFaculty Sandbox · 10W
●Path 01: Cloud Commercial LLM Dispatch Pipeline

General courses and humanities queries route via campus core switch to the API Gateway for quota deduction and prompt sanitization, passing through AiR encrypted tunnels to external cloud LLMs with end-to-end telemetry.

●Path 02: On-Premise Local Models & Zero IP Leakage Pipeline

Confidential research and lab practicum queries route to local AiW 6-GPU hosts and AiW-V servers running local 70B models. Exam banks, unpublished dissertations, and proprietary data stay 100% on campus with zero token fees.

●Path 03: Student Lab Quota & Fail-Safe Pipeline

High-concurrency student lab calls are authenticated against scoped course keys with daily limits. If a student runs an infinite error loop, the gateway triggers automatic circuit breaking after 10 errors to protect the class budget.

Boundary Layer

AiR AI Cloud Gateway Router

Deployed at the physical boundary between campus intranet and external model providers. Rejects unauthorized inbound probing and establishes encrypted tunnels for compliance-cleared model APIs.

12W Passive Die-Cast AluminumDual GbE Isolated Egress
Core Management Hub

ALNETS Enterprise AI API Gateway(Hardware Upcoming)

The central traffic dispatcher and token meter for all campus AI requests. Manages cloud & on-premise model pools, 4-tier quotas, prompt sanitization, automatic failover, and audit logs for grant accounting.

Cloud & On-Premise Multi-Model100% OpenAI Protocol CompatibleSub-second Circuit Breaking & Failover
On-Premise Compute

AiW 6-GPU Compute Host / AiW-V

Installed in university server rooms or research racks. Built for high-throughput multi-model parallel inference, running 70B open-weights offline. Exam data and research prompts route here with zero data leakage.

6-GPU High-Bandwidth ParallelismZero Marginal Token OPEX · 70B LLMECC Reliability · Zero IP Leakage

MODEL ALLOCATION & TOKEN SIZING

Campus Multi-Tier Model Allocation & Token Governance Matrix

Tailored model portfolios matching academic responsibilities, preventing overspending while empowering research diversity:

Academic OrganizationAllocated Model EngineQuota & Rate LimitsApplication Diversity & Security
Undergraduate General AI Courses
(e.g. 150+ students)
Cloud Frontier Fast LLM
(DeepSeek-V3 / Flash)
• 500K Tokens / student / month
• Max 5 RPM
• 10x error circuit breaker
High concurrency student labs; bulk-provisioned at semester start, auto-revoked upon final grading.
Computer Science & AI Majors
(e.g. Code, Tuning & Practicum)
Local AiW 6-GPU Model Engine
(Open-weight 70B / Qwen-72B / Code LLM)
• On-premise: 0 token cost
• Full function calling enabled
• High 30-50 RPM
Full parameter control and fine-tuning; local compute eliminates cloud bills while student code and exams stay private.
Confidential Defense & Medical Labs
(e.g. National Grants / Defense)
Dedicated Local AiW 6-GPU / AiW-V
(Air-gapped 70B Deep Reasoning LLM)
• Dedicated private pool
• Elastic concurrency
• Mandatory air-gapped route
100% Academic Confidentiality:
Unpublished research and medical data remain air-gapped on campus to satisfy compliance audits.
Humanities, Business & Law
(e.g. Literature & Multilingual)
Cloud Frontier Reasoning Models
(Claude / OpenAI Authorized Channels)
• Funded via grant budget pool
• 10-20 RPM throttle
• Citation grounding enabled
Long-context foreign literature review and multilingual drafting via AiR encrypted channels with clean egress.
Academic Affairs & Campus Administration
(e.g. Course FAQ & Admissions)
Campus Private RAG QA Engine
(Campus Knowledge Grounded)
• Unified campus base quota pool
• Strict prompt filter & hallucination checks
24/7 student service grounded in verified campus rules, with zero cloud exposure of unpublished records.

FIELD SCENARIOS

Three Authentic Academic Deployment Scenarios

Solving friction across large-class labs, confidential lab research, and finance grant audits:

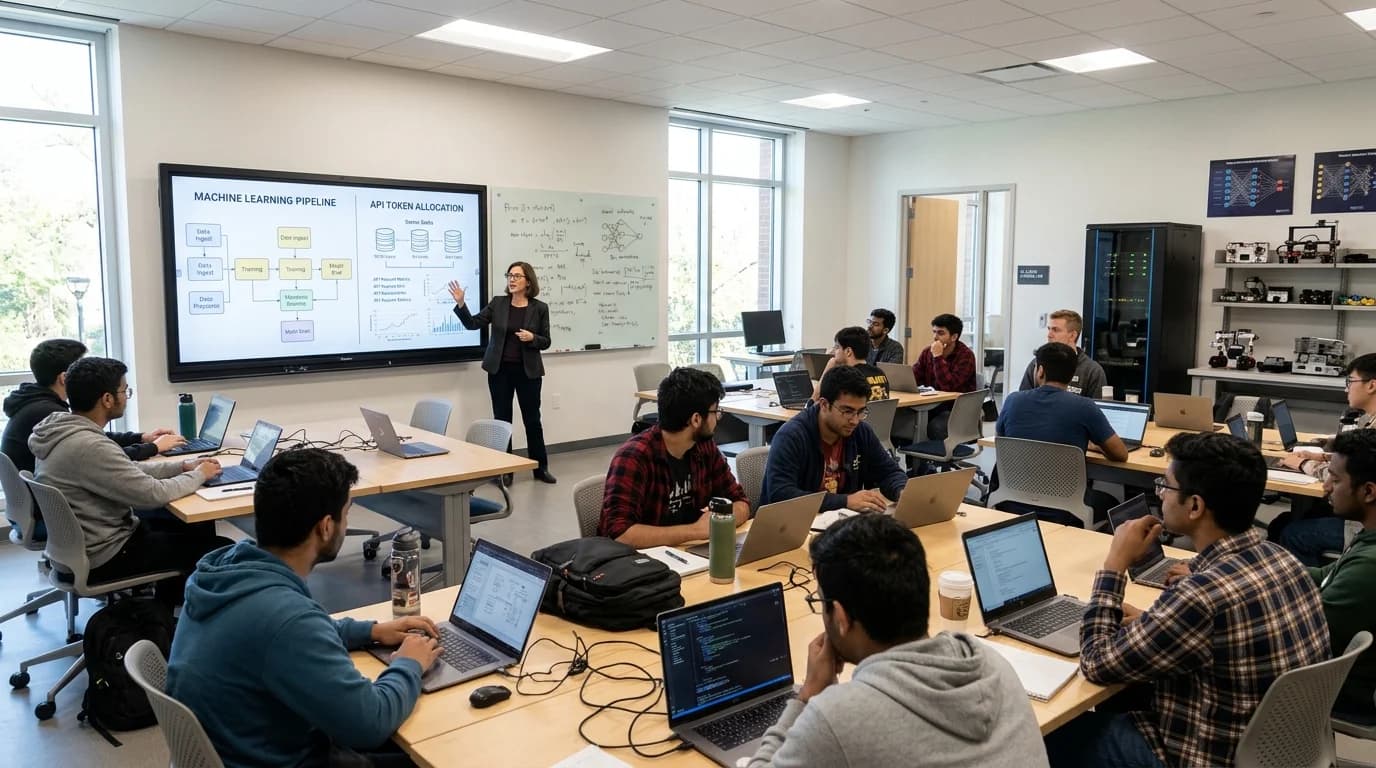
University AI lab classroom with students and professor
Scenario 01

150-Student Lab: Automated Key Bulk-Issuance & Circuit-Breaking

A university offering an introductory AI course to 180 students deployed the ALNETS gateway. Instructors imported the student roster and bulk-issued 180 individual keys capped at 500K tokens monthly. When one student created an infinite request loop, the gateway circuit breaker kicked in after 10 consecutive errors, suspending only that student for 15 minutes while protecting the class budget and remaining 179 learners.

✓ Automated Student Roster Ingestion✓ Rigid Per-Student Ceilings✓ Sub-Second Error Loop Isolation
Scenario 02

Defense & National Grants: Air-Gapped AiW 6-GPU Compute

A national key laboratory researching proprietary polymers air-gapped their experimental formulas. The gateway automatically routes prompts containing raw experimental data to on-premise AiW 6-GPU compute hosts running local 70B models, while sending general literature searches to cloud LLMs—combining agility with strict compliance and zero token fees.

✓ 100% On-Premise Data Retention
Scenario 03

Finance Grant Accounting: Project-Level Audit Statements

Professors frequently struggle with grant expense auditing. With ALNETS, each grant is issued an isolated API key tagged with the grant code (e.g. NSFC-2026-XXXX). At month end, the system generates itemized PDF audit logs detailing timestamps, token counts, and cost conversions for seamless finance clearance.

✓ Grant-Code Tagged Cost Centers

PRODUCT MATRIX

Hardware-Software Synergy Matrix

From lightweight gateway software to high-performance passive hardware appliances, mix and match as your campus grows:

ProductRole & FocusKey Engineering SpecsDeployment Stage
ALNETS Enterprise AI API Gateway
(Hardware Upcoming)
Unified Campus Gateway Hub (Dual-Engine)
Aggregates cloud & on-premise models, 4-tier token water taps, compliance filtering & account pooling
GbE/10GbE wire-speed forwarding; sub-ms dispatch with encrypted logsStage 1 (Mandatory Base)
AiW 6-GPU Compute Host
(In Planning · Upcoming)
Primary On-Premise Multi-GPU Compute Host
High-throughput local multi-model parallel inference; 100% data privacy with zero token fees
6-GPU high-bandwidth topology; high-density serving; verified for 70B-class modelsStage 3 (Core Compute Base)
AiR AI Cloud Gateway Router →Secure Cloud Egress Gateway
Physical boundary between campus LAN and public WAN with zero unvetted ingress
12W fanless aluminum passive thermal; dual GbE egress with TLS tunnelingStandard for All Stages
AiW-V High-VRAM Workstation →On-Premise 70B Compute Workstation
Runs open 27B/70B models locally with zero external API fees and complete privacy
32GB/64GB high-speed VRAM; enterprise ECC memory; whisper-quiet thermalsStages 2 & 3 (Expansion)
AiA 10W Dedicated Agent Host →24/7 Dedicated Agent Sandbox Host
Persistent literature tracking and experiment scripts independent of laptops
~10W ultra-low idle; compact desktop footprint; physical OS-level sandboxStage 4 (Faculty Seats)

READINESS & CRITERIA

Readiness Checklist & Formal Acceptance Criteria

Explicit checklists prior to deployment, ensuring transparent boundaries and measurable outcomes:

Pre-Deployment Checklist

  • University cloud AI accounts, upstream API credentials, or existing local servers
  • Pilot departments, course rosters, or designated research lab member lists
  • Campus data center rack space or departmental lab desks for AiW 6-GPU hosts and workstations

Acceptance Criteria

  • Departments query authorized cloud or local models via gateway keys without exposing upstream credentials
  • Confidential lab prompts route exclusively to local AiW compute nodes with zero cloud data egress
  • Different departments access tailored models, with large-class student calls obeying quota limits and circuit-breaking
  • Token usage reports exportable by department, faculty, course, and project code for finance audit