ALNETS · Deployment guides
Agent host and model inference: separate the runtime from compute
An Agent host runs the client, tools and task workspace. Inference comes from a centralized API gateway or local model service. Decoupling the runtime ensures clean cost control.
Short answer
Treat the Agent host as a dedicated task runtime, not model training or inference hardware. Decide where the model runs, then plan the client host, model service and network separately.
What the Agent host does
The host runs the Agent client, tools and task directory in a dedicated user environment. For enterprise use, plan one host per user. Configure accounts, tool permissions and data access to organizational requirements.
- Confirm clients, tools and dependencies.
- Define work directories and enterprise data boundaries.
- Define interruption, output-saving and human-intervention handling.
Choose an inference path
| Path | Considerations | Architecture Benefits |
|---|---|---|
| Unified API Gateway Cloud Inference | An external model service is authorized via gateway. | Centralized token auditing; keys never touch edge PCs. |
| Local Edge Model Service | Sensitive enterprise data must remain on LAN. | Sub-second latency with zero WAN bandwidth cost. |
Keep connectivity in scope
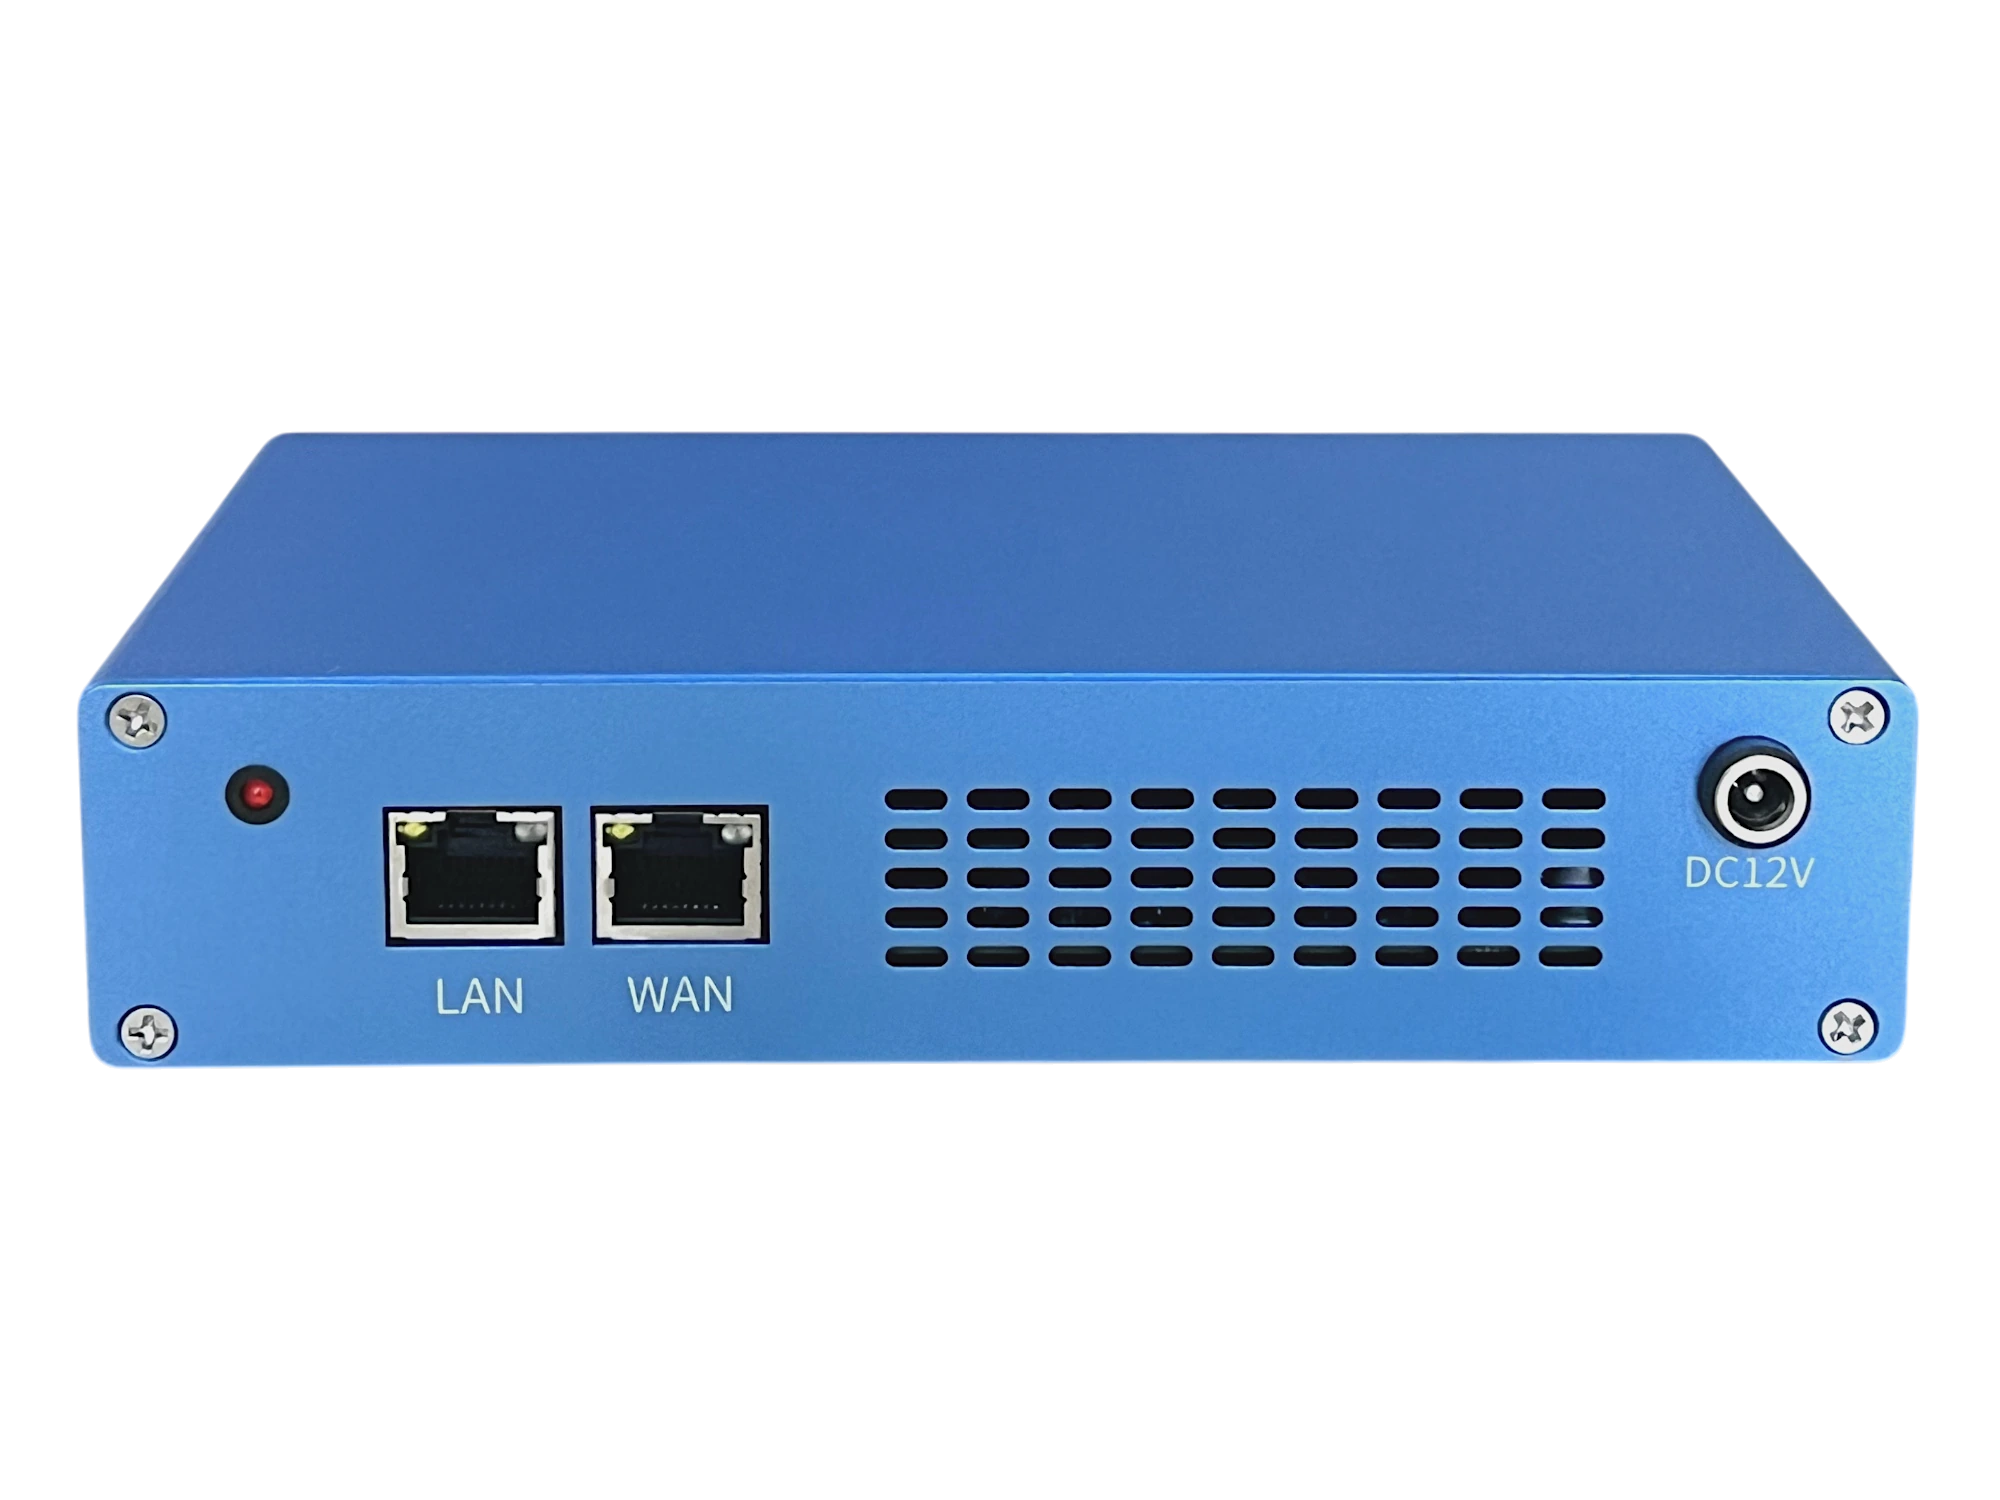
AiR is optional, depending on external-connectivity needs. The local LAN directly carries calls to on-prem model services; when calling external models, AiR and the enterprise API gateway provide secure tunneling.
ARCHITECTURE & HARDWARE SYNERGY
Recommended Products & Bundles
Hardware appliances, gateways, and collaborative suites referenced in this guide:
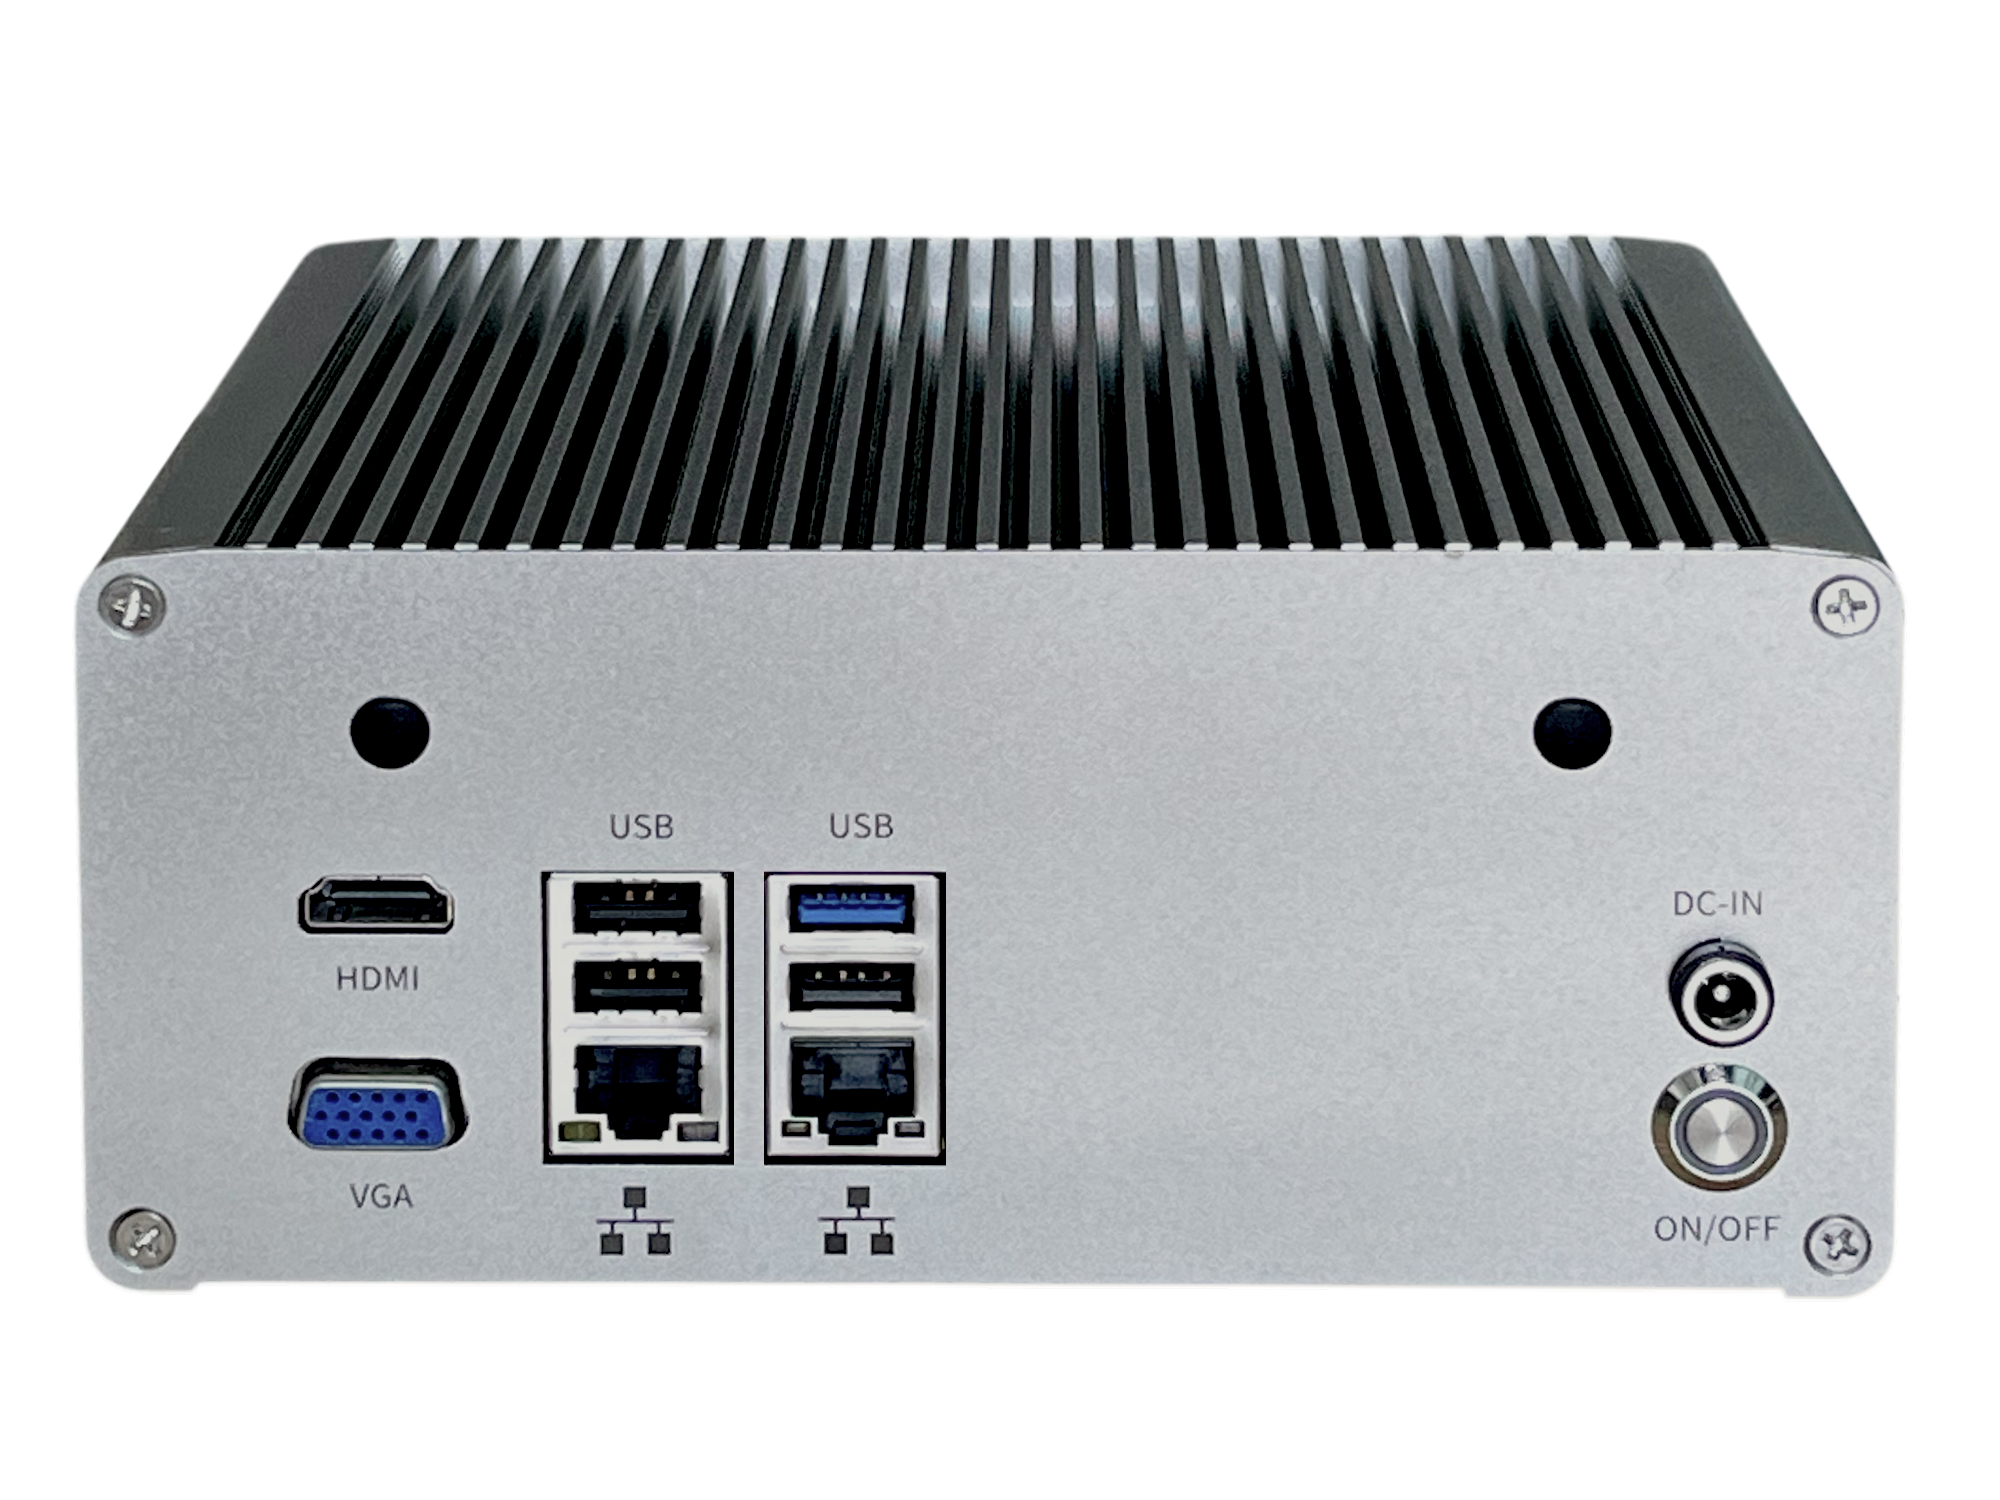
AiA AI Agent Host
Whisper-quiet edge host designed for 24/7 autonomous AI Agent execution with ultra-low 10W power.
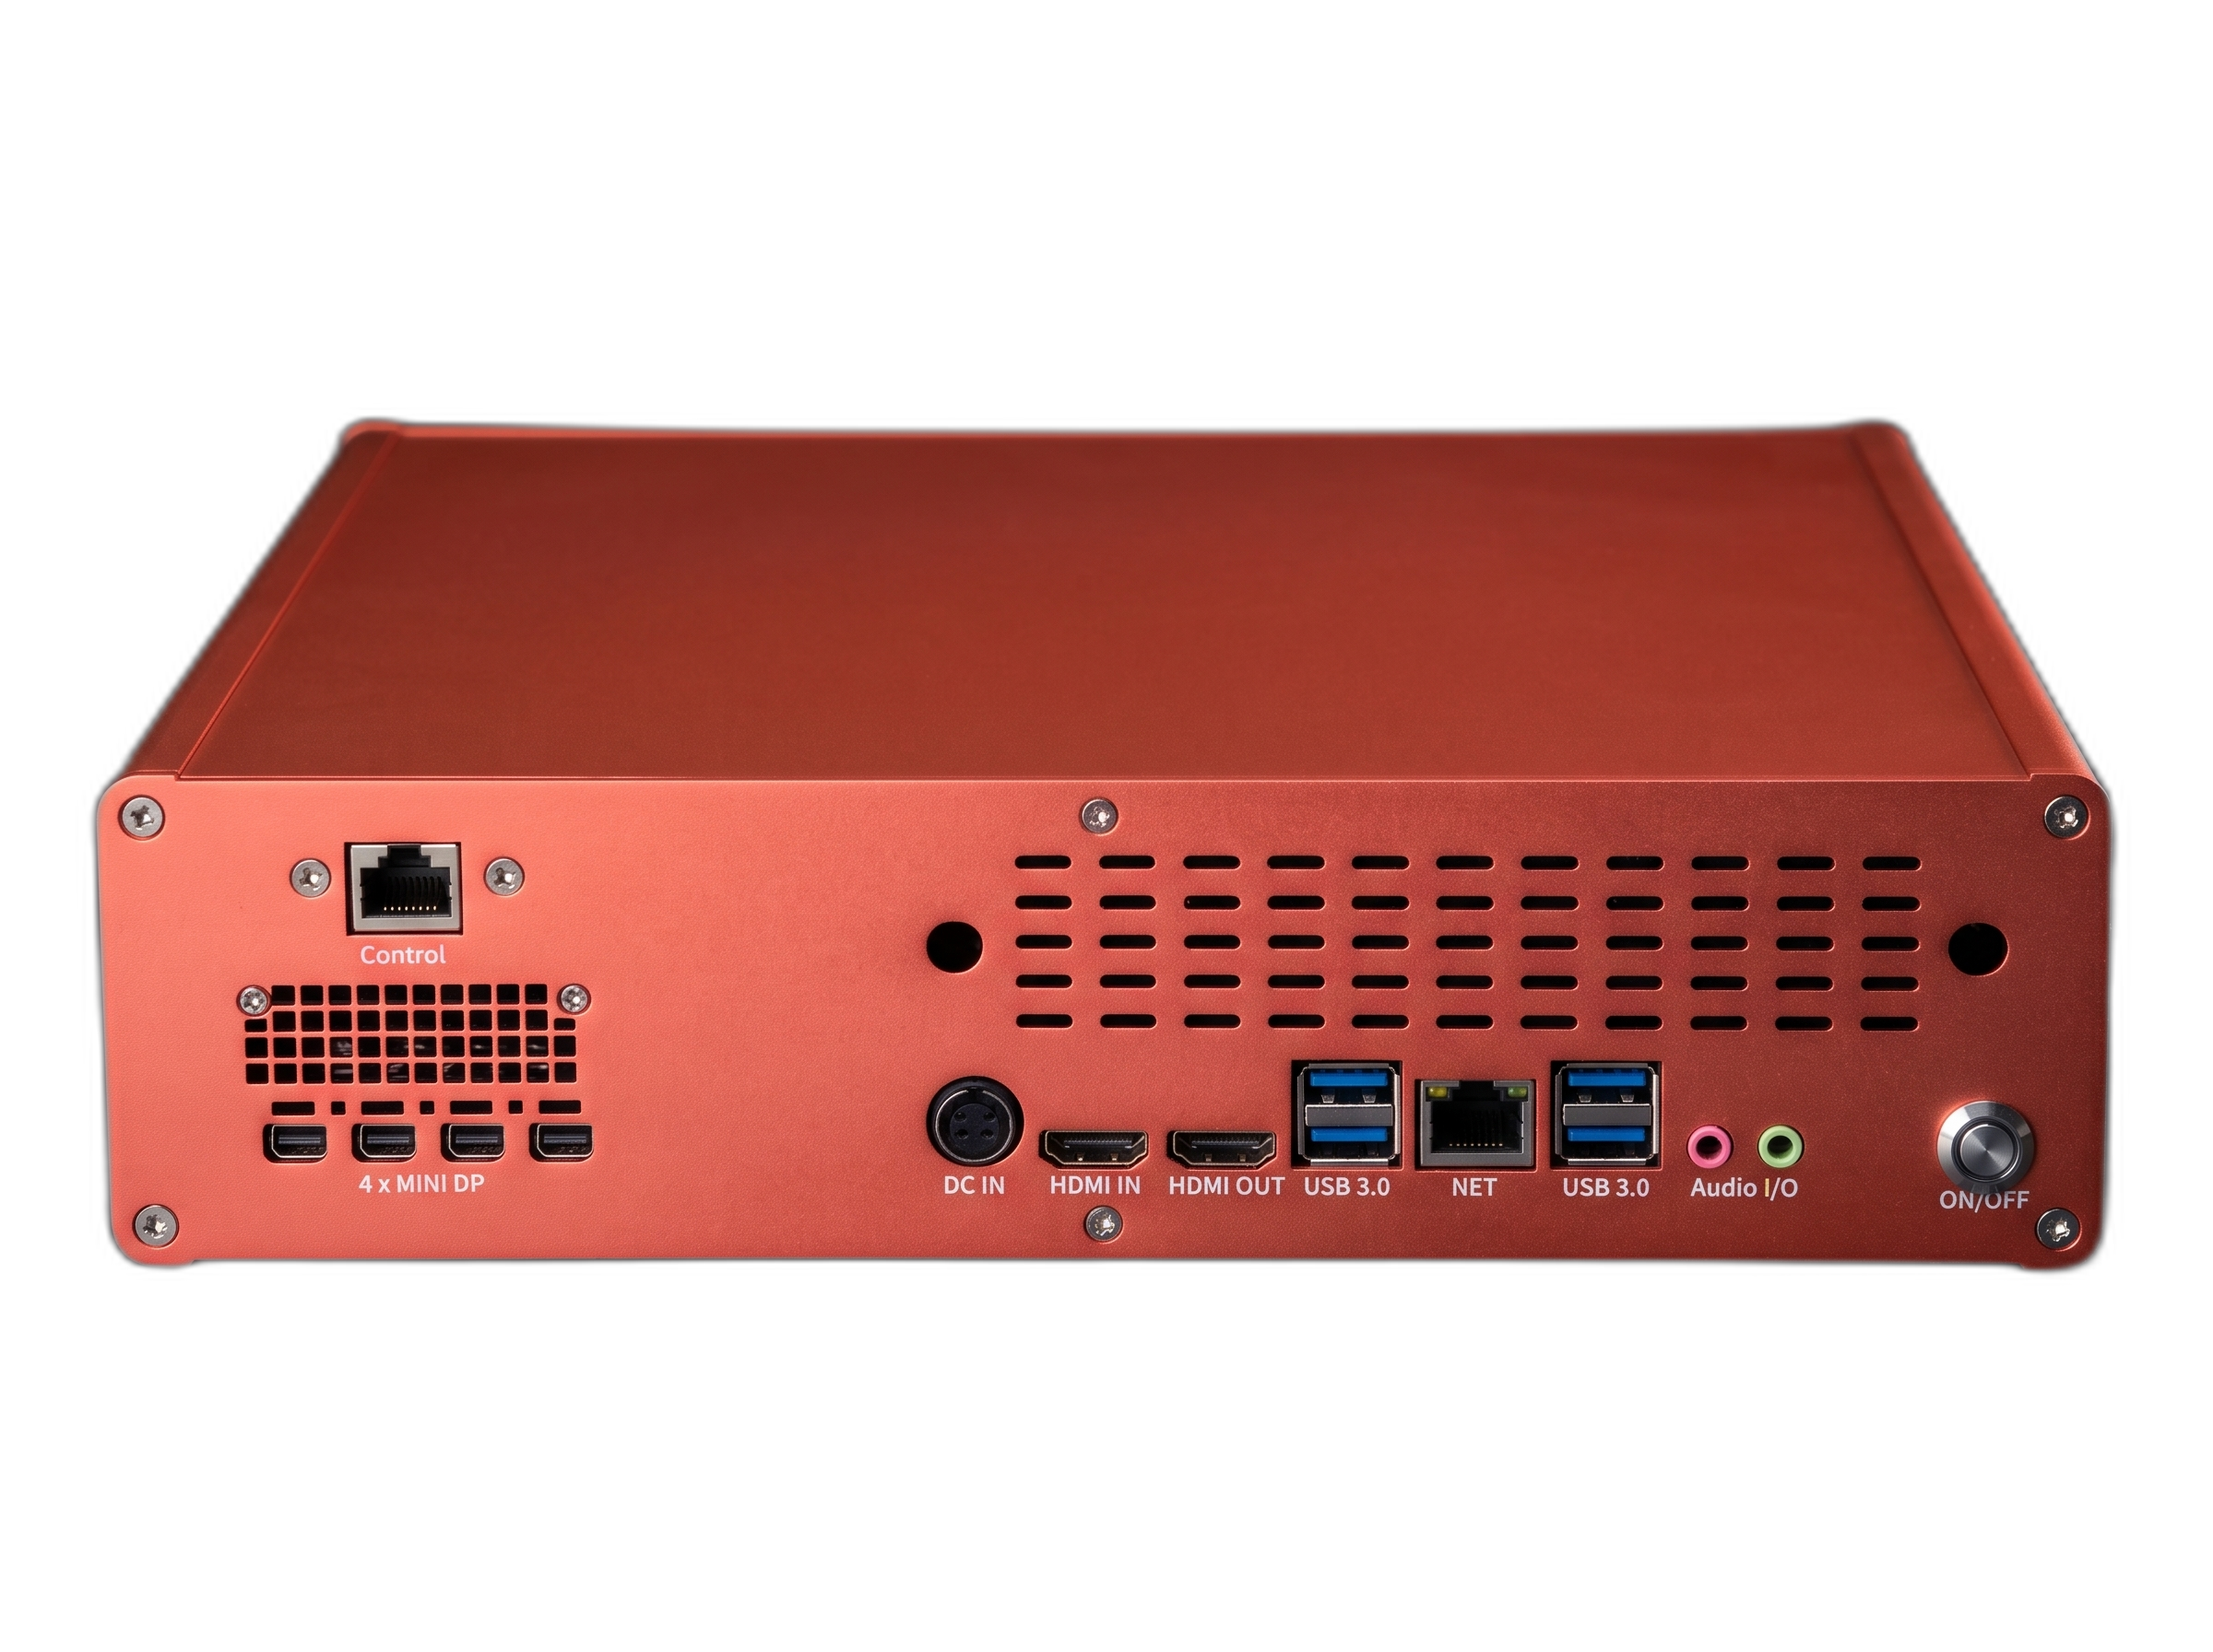
AE-2000 Industrial Edge AI Computer
Local AI compute for industrial and commercial sites, with two system configurations. Both use an NVIDIA RTX 2000 Ada GPU with 16GB GDDR6 ECC memory.
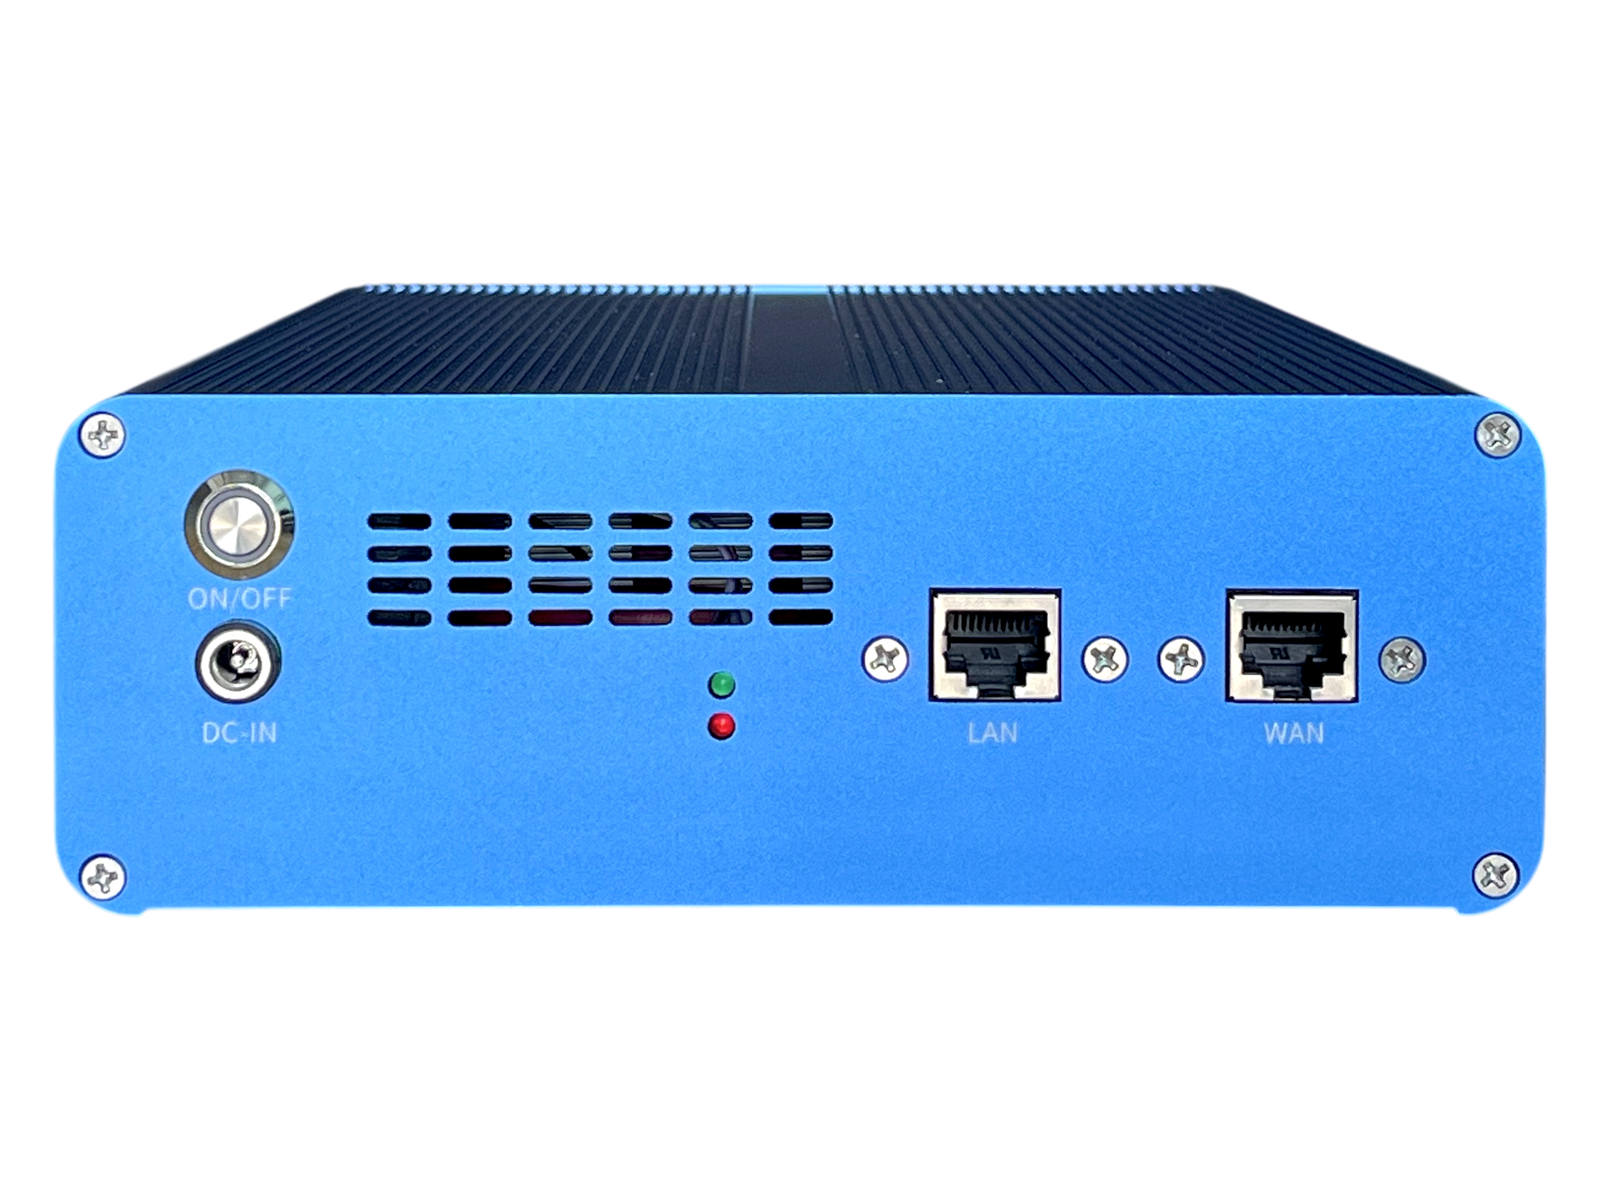
AiR AI Cloud Gateway Router
Secure encrypted tunneling, multi-wan routing and remote access gateway for on-site AI deployments.
Enterprise AI API Gateway
Centralized multi-model routing, token quota metering, concurrency throttling, and private auth. In planning · Coming soon.
Agent Workspace solution
Integrated hardware topology, security boundary, and turnkey suite
AiA Agent Workspace Host
Integrated hardware topology, security boundary, and turnkey suite
AiR AI Cloud Gateway Router
Integrated hardware topology, security boundary, and turnkey suite
7×24 Dedicated Autonomous Agent Workspace
Deploy dedicated AiA agent hosts, AiR secure network egress, API Gateway per-employee model governance, and AE-2000 private knowledge retrieval—organizing role-specific models, docs, and continuous workspaces with full bespoke customization support.